Publications
Selected papers on AI hardware and software co-design, analog in-memory computing, neural architecture search, efficient LLM inference, and model optimization, with Google Scholar metrics.
SparseST: Exploiting Data Sparsity in Spatiotemporal Modeling and Prediction
SparseST cuts the compute cost of spatiotemporal data mining by exploiting sparsity in the data, not only in the model. Accurate ConvLSTM variants are expensive to run on edge devices, so SparseST skips redundant computation on spatially sparse frames and on the sparse first-order differences between adjacent frames. On an industrial anomaly-detection case study it reaches up to 85.67% acceleration with only a 9.4% reduction in model performance, with further results on Moving MNIST.
J Wu, H Benmeziane, K El Maghraoui, L Liu, Y Wang
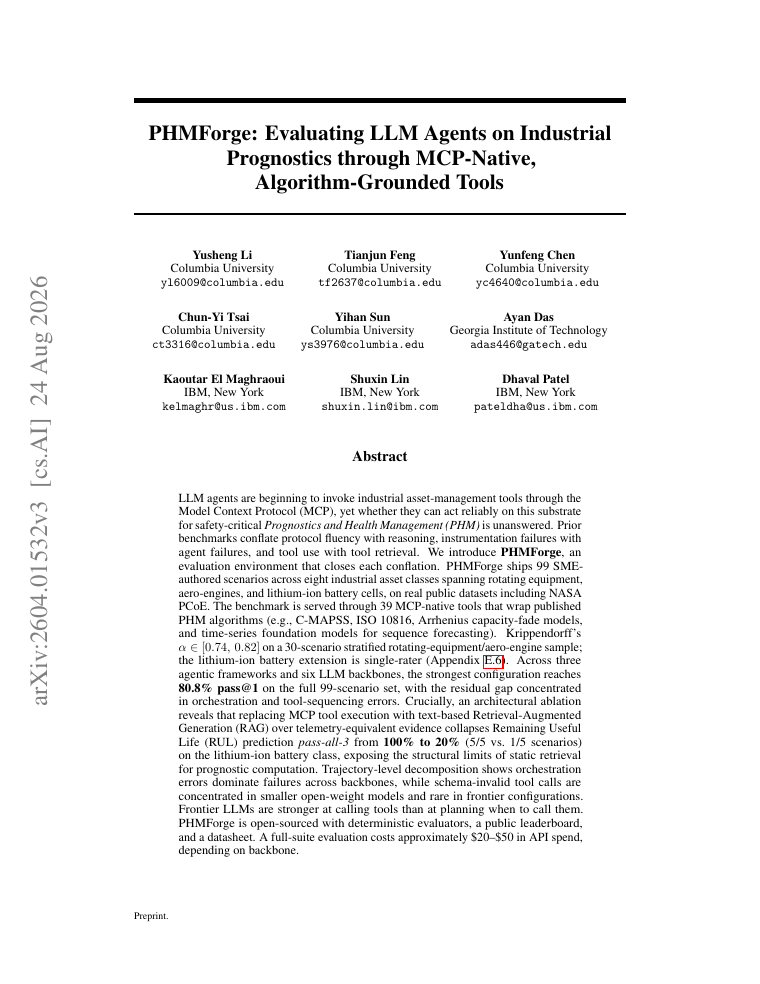
PHMForge: Evaluating LLM Agents on Industrial Prognostics through MCP-Native, Algorithm-Grounded Tools
A benchmark that tests whether LLM agents can act reliably on prognostics and health management tasks by calling real algorithms through MCP rather than reasoning over text. It ships 99 expert-authored scenarios across eight asset classes, served through 39 MCP-native tools that wrap published PHM algorithms such as C-MAPSS, ISO 10816, and Arrhenius capacity-fade models. Built by Columbia HPML students; the strongest configuration reached 80.8 percent pass@1, and an ablation showed static text retrieval cannot replace running the algorithms.
Y Li, T Feng, Y Chen, CY Tsai, Y Sun, A Das, K El Maghraoui, S Lin, D Patel
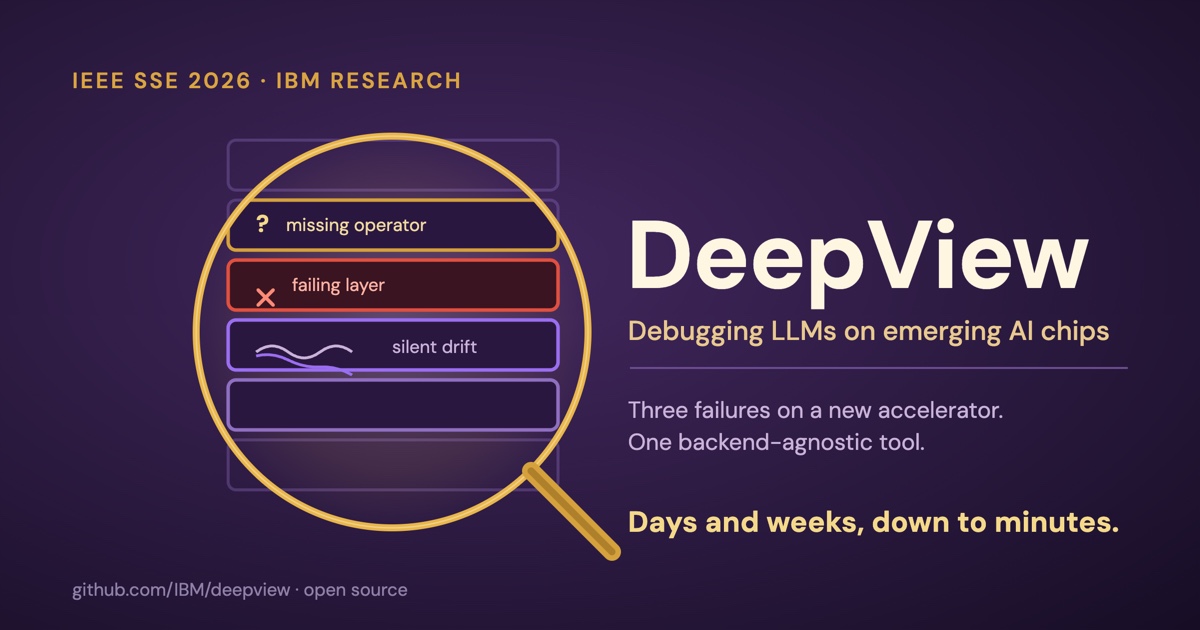
DeepView: A Generalizable Debugging Methodology for Enabling Large Language Models on Emerging AI Accelerators
A generalizable, open-source debugging methodology for bringing large language models up on new AI accelerators. DeepView isolates the small set of failures that block model bring-up on a fresh chip and cuts diagnosis from days or weeks to minutes, generalizing across hardware backends rather than being tied to one vendor's stack.
K El Maghraoui, J Murray, S Goel, A Chakraborty, P Naik, S Suneja, et al.
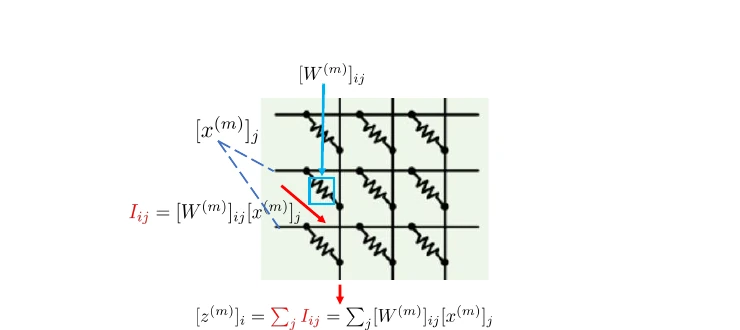
On the Convergence Theory of Pipeline Gradient-based Analog In-memory Training
First convergence theory for asynchronous pipeline SGD on analog in-memory computing (AIMC) accelerators. Despite stale weights and asymmetric update bias, Analog-SGD-AP matches the iteration complexity of digital SGD up to non-dominant terms and increases computation density from B/(M+B-1) to 1, delivering near-linear wall-clock speedup validated on ResNet/CIFAR with AIHWKit.
Z Wu, Q Xiao, T Gokmen, H Tsai, K El Maghraoui, T Chen
Efficient Quantization of Mixture-of-Experts with Theoretical Generalization Guarantees
A theoretically grounded expert-wise mixed-precision quantization strategy for Mixture-of-Experts models. Allocates bit-width per expert based on changes in router L2 norm and intra-neuron variance during training, with provable generalization bounds. Validated on Switch Transformer and Mixtral with higher accuracy and lower inference cost than prior MoE quantization methods.
MNR Chowdhury, K El Maghraoui, H Tsai, N Wang, GW Burr, L Liu, M Wang
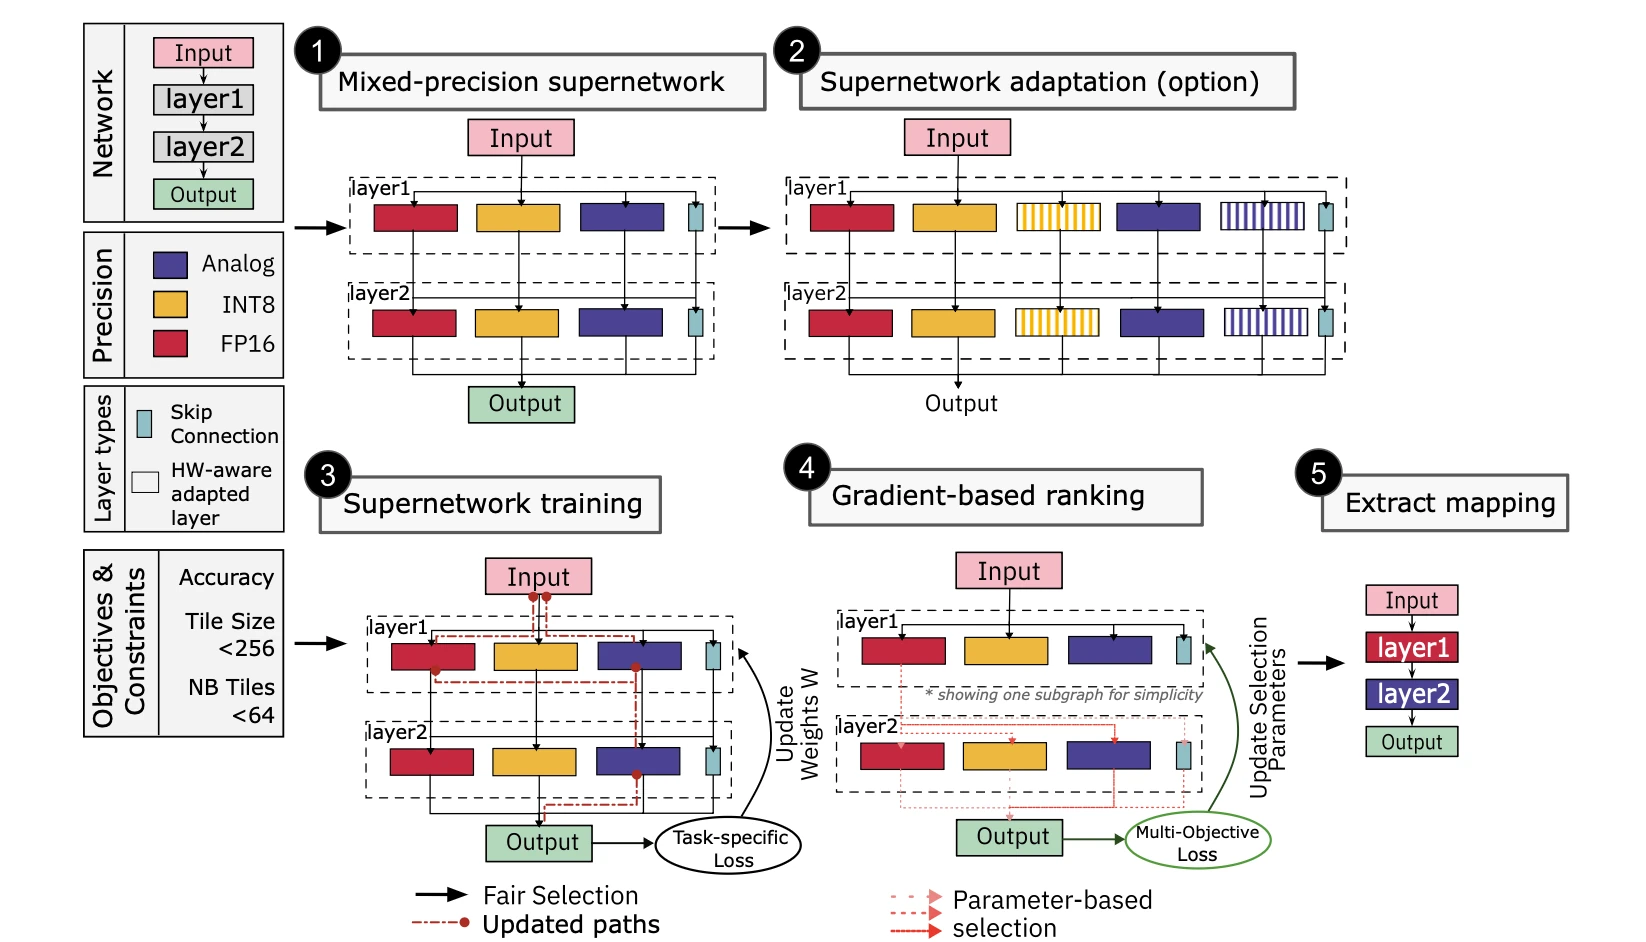
Supernetwork-Based Efficient Mapping of Deep Learning Applications to Mixed-Precision Hardware Using Model Adaptation
Introduces Mixed-Precision Supernetwork (MPS), a unified framework for training mixed-precision supernetworks that seamlessly map deep learning models to heterogeneous analog-digital hardware. MPS produces mappings ~2.2x faster and achieves ~3.4% higher accuracy over fully analog approaches while improving energy efficiency by mapping up to 80% of weights to analog hardware.
H Benmeziane, C Lammie, I Boybat, M Rasch, M Le Gallo, A Vasilopoulos, H Tsai, GW Burr, V Narayanan, K El Maghraoui, A Sebastian
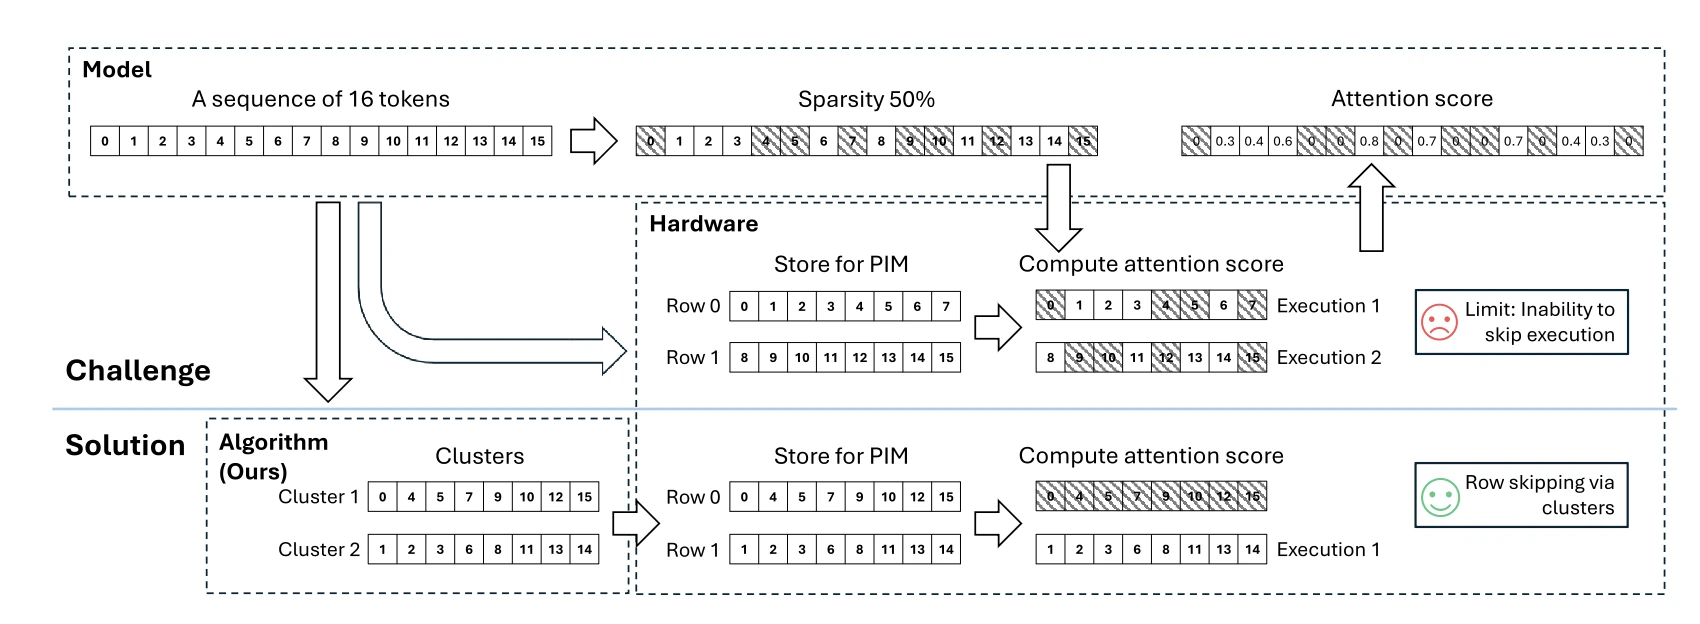
STARC: Selective Token Access with Remapping and Clustering for Efficient LLM Decoding on PIM Systems
A novel approach for efficient large language model decoding on Processing-In-Memory systems, using selective token access with remapping and clustering to dramatically reduce memory bottlenecks.
Z Fan, Y Liu, G Gagnon, Z Liu, Y Hou, H Benmeziane, K El Maghraoui, L Liu
Analog Foundation Models
Studies how foundation-model–scale LLMs behave on analog in-memory computing hardware. Introduces training and adaptation methods that close most of the accuracy gap between digital and analog inference at billion-parameter scale, demonstrating that modern foundation models can run efficiently on analog AIMC accelerators.
J Büchel, I Chalas, G Acampa, A Chen, O Fagbohungbe, H Tsai, K El Maghraoui, M Le Gallo, A Rahimi, A Sebastian
NoRA: Noise-Optimized Rescaling of LLMs on Analog Compute-in-Memory Accelerators
Noise-optimized rescaling for deploying large language models on analog compute-in-memory accelerators. Reduces accuracy loss caused by analog noise during LLM inference by adapting layer-wise rescaling factors to the device noise profile, improving robustness without retraining.
Y Hou, H Tsai, K El Maghraoui, T Gokmen, GW Burr, L Liu
EvidenceMoE: A Physics-Guided Mixture-of-Experts with Evidential Critics for Advancing Fluorescence Detection and Ranging in Scattering Media
Introduces a Mixture-of-Experts architecture combined with evidential critics for robust fluorescence detection and ranging in challenging scattering environments, advancing scientific imaging capabilities.
I Erbas, F Demirkiran, K Swaminathan, N Wang, NI Nizam, N Yuan, S Ragab, L Chavez, K El Maghraoui, X Intes, V Pandey
Ultra-Low Precision 4-bit Training of Deep Neural Networks
Novel techniques and numerical representation formats to scale the precision of training systems from 8-bits to 4-bits, introducing adaptive Gradient Scaling for quantized gradients.
X Sun, N Wang, CY Chen, J Ni, A Agrawal, X Cui, S Venkataramani, K El Maghraoui, et al.
A Flexible and Fast PyTorch Toolkit for Simulating Training and Inference on Analog Crossbar Arrays
A comprehensive PyTorch toolkit enabling efficient simulation of analog in-memory computing for neural network training and inference on crossbar arrays.
MJ Rasch, D Moreda, T Gokmen, M Le Gallo, F Carta, C Goldberg, K El Maghraoui, et al.
A Comprehensive Survey on Hardware-Aware Neural Architecture Search
An extensive survey and taxonomy of hardware-aware NAS methods, covering search strategies, hardware metrics, and deployment considerations across diverse platforms.
H Benmeziane, K El Maghraoui, H Ouarnoughi, S Niar, M Wistuba, et al.
ModelOps: Cloud-Based Lifecycle Management for Reliable and Trusted AI
A framework for managing the full lifecycle of AI models in the cloud, addressing reliability, trust, and operational efficiency for enterprise AI deployments.
W Hummer, V Muthusamy, T Rausch, P Dube, K El Maghraoui, A Murthi, et al.
Using the IBM Analog In-Memory Hardware Acceleration Kit
Comprehensive guide to the IBM AIHWKit for neural network training and inference on analog in-memory computing hardware, enabling energy-efficient AI acceleration.
M Le Gallo, C Lammie, J Büchel, F Carta, O Fagbohungbe, C Mackin, K El Maghraoui, et al.
Neural Architecture Search for In-Memory Computing-Based Deep Learning Accelerators
A review of NAS techniques tailored for in-memory computing accelerators, bridging the gap between neural network design and emerging hardware paradigms.
O Krestinskaya, ME Fouda, H Benmeziane, K El Maghraoui, A Sebastian, et al.
Deep Compression of Pre-trained Transformer Models
Techniques for dramatically compressing pre-trained transformer models while maintaining accuracy, enabling efficient deployment on resource-constrained hardware.
N Wang, CCC Liu, S Venkataramani, S Sen, CY Chen, K El Maghraoui, et al.
Multi-Objective Hardware-Aware Neural Architecture Search with Pareto Rank-Preserving Surrogate Models
A novel multi-objective NAS framework using Pareto rank-preserving surrogate models to efficiently discover optimal architectures across multiple hardware constraints.
H Benmeziane, H Ouarnoughi, K El Maghraoui, S Niar
AnalogNAS: A Neural Network Design Framework for Accurate Inference with Analog In-Memory Computing
An end-to-end NAS framework that searches for neural architectures matched to analog in-memory computing hardware. AnalogNAS produces models that are noise-resilient and energy-efficient on AIMC, narrowing the accuracy gap with digital inference for image and language tasks.
H Benmeziane, C Lammie, I Boybat, M Rasch, M Le Gallo, H Tsai, R Muralidhar, S Niar, H Ouarnoughi, V Narayanan, A Sebastian, K El Maghraoui
Design of Analog-AI Hardware Accelerators for Transformer-Based Language Models
End-to-end design of analog-AI accelerators for transformer-based language models. Covers device-, circuit- and architecture-level co-design needed to run BERT- and GPT-class workloads on analog in-memory computing tiles, with measured accuracy and energy results from prototype hardware.
GW Burr, H Tsai, W Simon, I Boybat, S Ambrogio, CE Ho, ZW Liou, M Rasch, J Büchel, P Narayanan, K El Maghraoui, et al.